
An eval harness for AI coding agents. Define tasks, run any agent, score with deterministic scripts, LLM judges, or human reviewers.
Works with Gemini CLI, Claude Code, Codex CLI, OpenCode, any ACP-compatible agent, or any command-line tool — with or without Agent Skills.
See examples/ — superlint (simple) and angular-modern (TypeScript grader).
Prerequisites: Node.js 20+, Docker
npm i -g skillgrade1. Initialize — scaffold an eval.yaml in any directory:
cd my-evals/
skillgrade init
If a SKILL.md is present and an API key is set, init generates AI-powered tasks tailored to the skill. Otherwise, it creates a ready-to-edit template.
2. Edit — define your tasks in eval.yaml (see eval.yaml Reference).
3. Run:
GEMINI_API_KEY=your-key skillgrade --smokeThe agent is auto-detected from your API key: GEMINI_API_KEY → Gemini, ANTHROPIC_API_KEY → Claude, OPENAI_API_KEY → Codex. Override with --agent=claude.
4. Review:
skillgrade preview          # CLI report
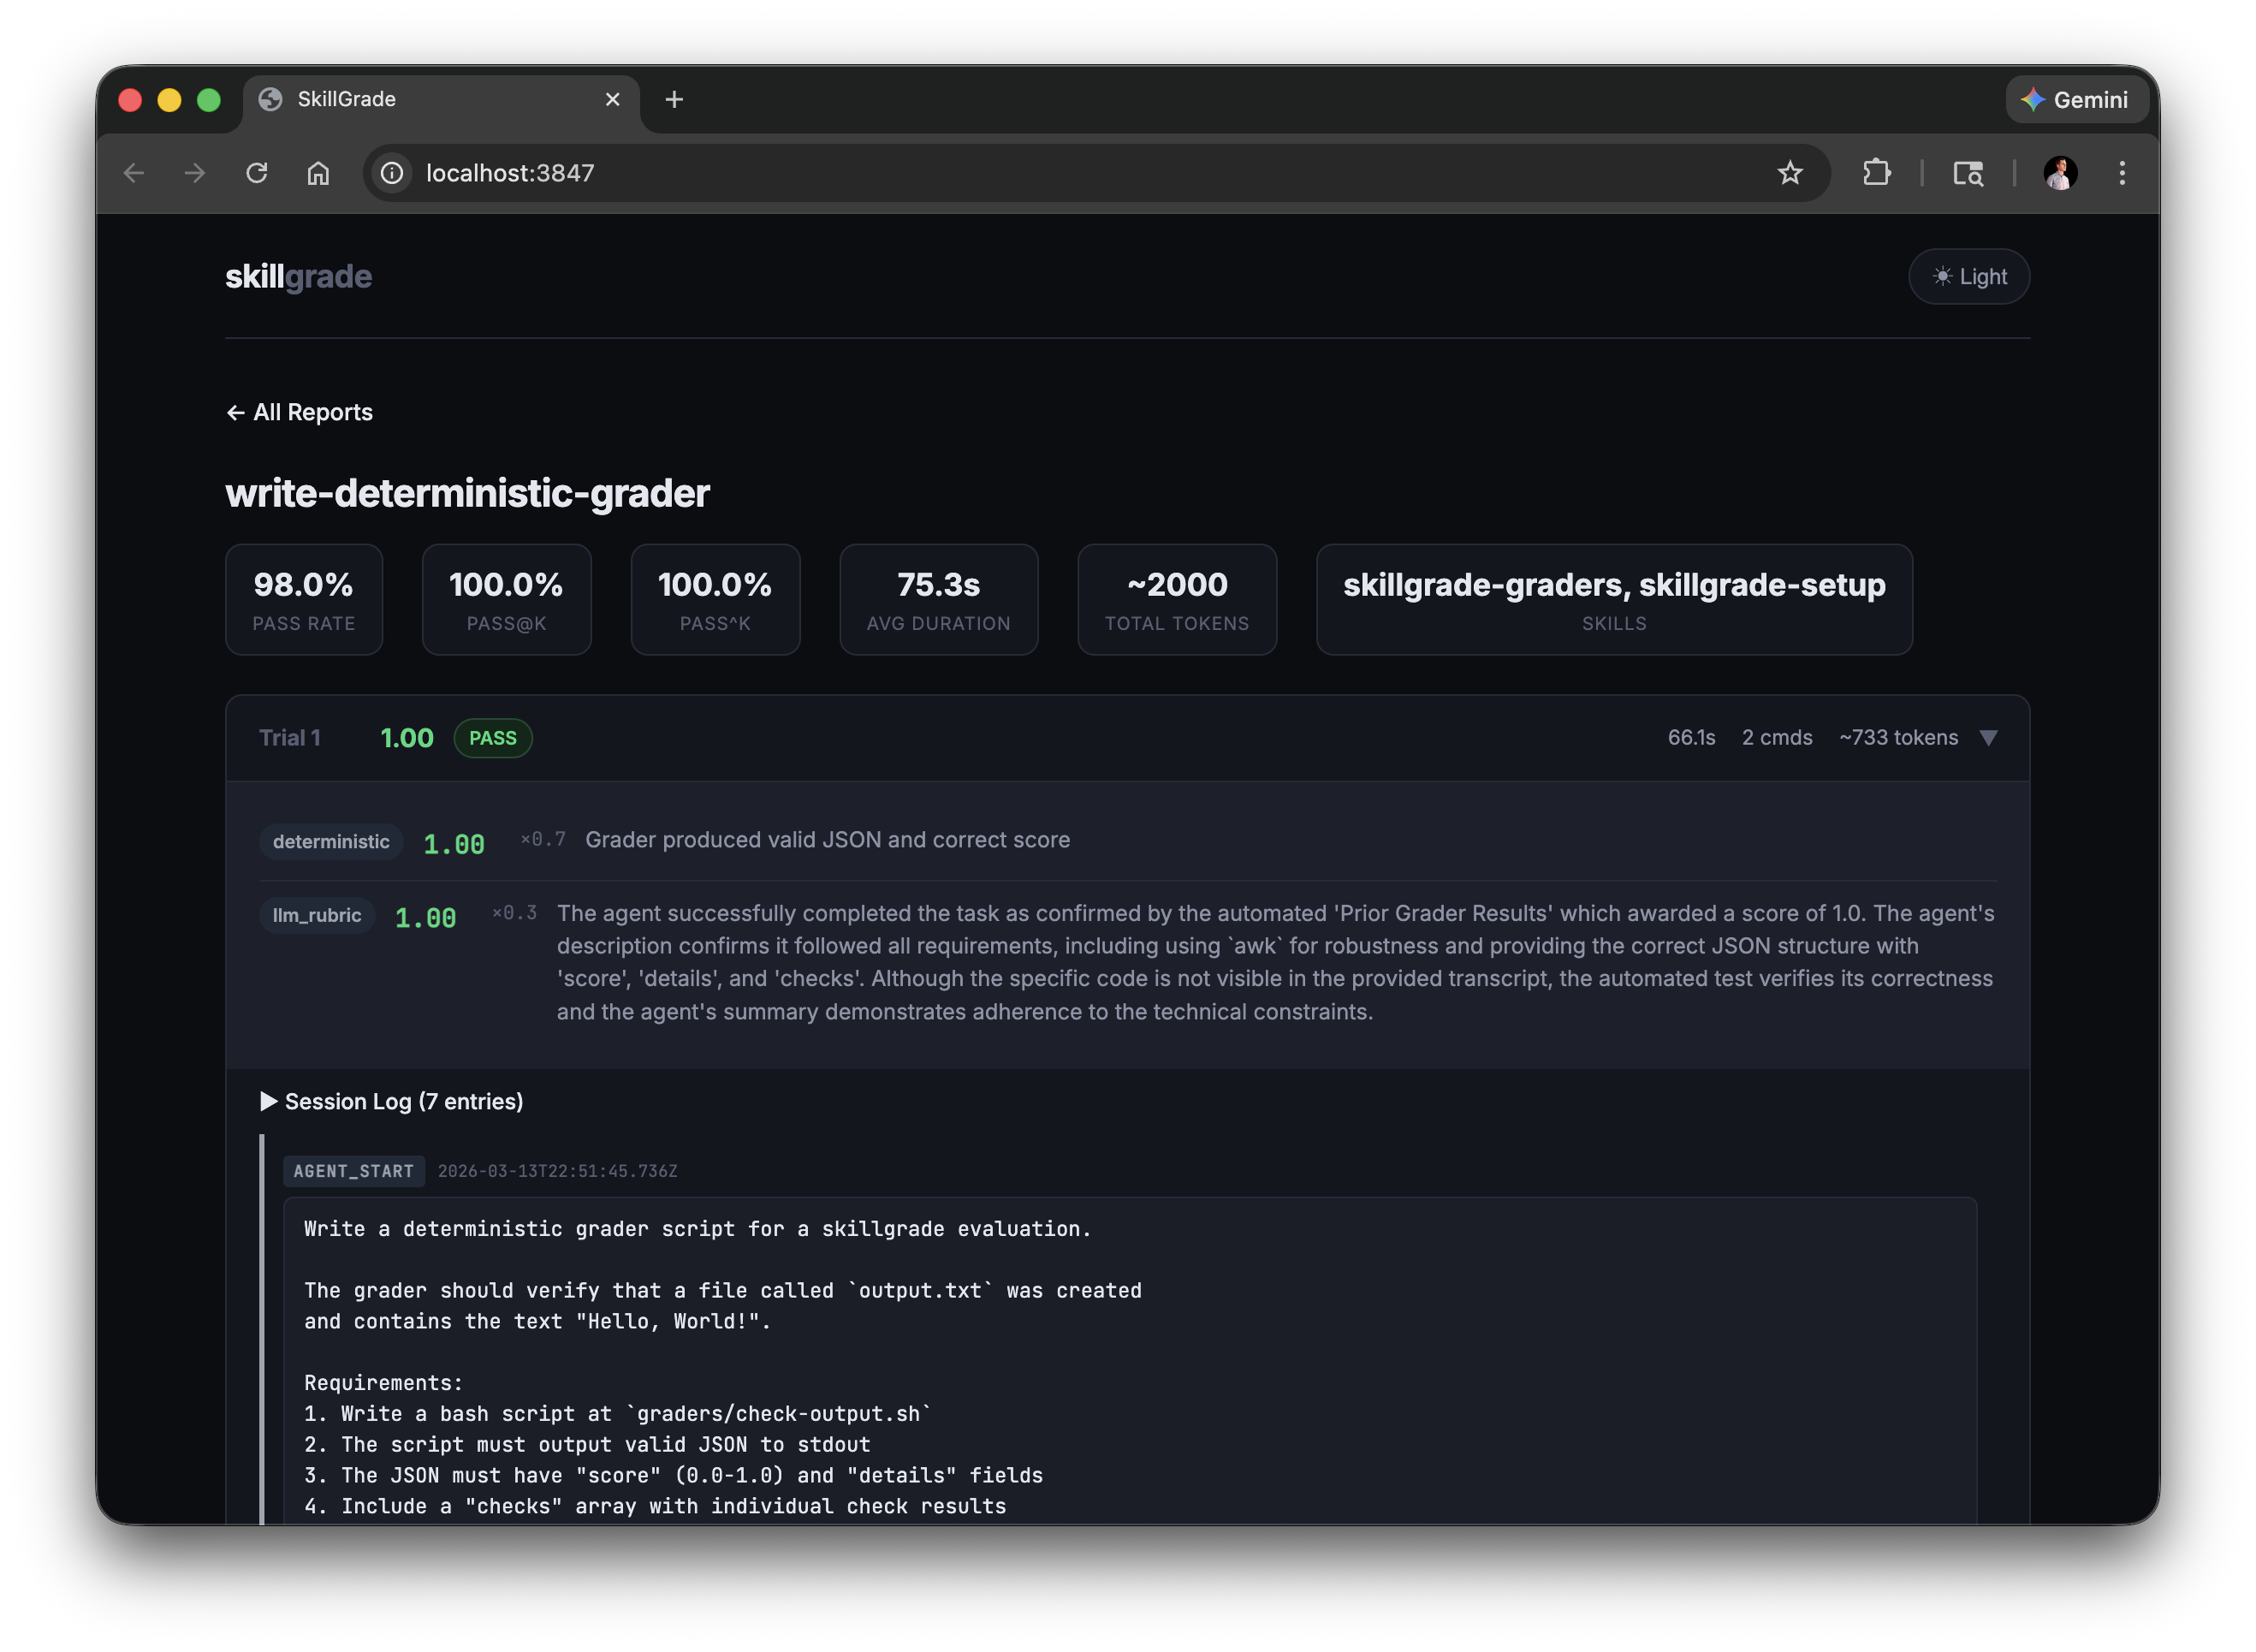
skillgrade preview browser  # web UI → http://localhost:3847
Reports are saved to $TMPDIR/skillgrade/<eval-name>/results/. Override with --output=DIR.
| Flag | Trials | Use Case |
|---|---|---|
--smoke |
5 | Quick capability check |
--reliable |
15 | Reliable pass rate estimate |
--regression |
30 | High-confidence regression detection |
| Flag | Description |
|---|---|
--eval=NAME[,NAME] |
Run specific evals by name (comma-separated) |
--grader=TYPE |
Run only graders of a type (deterministic, llm_rubric, or human) |
--trials=N |
Override trial count |
--parallel=N |
Run trials concurrently |
--agent=gemini|claude|codex|acp|opencode|command |
Override agent (default: auto-detect from API key) |
--model=NAME |
Model the agent answers with (gemini, claude, codex, opencode). Default: whatever the agent CLI is configured to use |
--provider=docker|local |
Override provider |
--acp-command=CMD |
ACP agent command (e.g., gemini --acp) |
--command=CMD |
Command to run for the command agent (e.g., node mycli.js) |
--opencode-agent=NAME |
OpenCode agent (build|plan|explore) |
--opencode-model=MODEL |
OpenCode model (provider/model format) |
--output=DIR |
Output directory (default: $TMPDIR/skillgrade) |
--format=FORMAT |
Export results (json, junit, csv, markdown — comma-separate for multiple) |
--validate |
Verify graders using reference solutions |
--ci |
CI mode: exit non-zero if below threshold |
--threshold=0.8 |
Pass rate threshold for CI mode |
--preview |
Show CLI results after running |
version: "1"

# Optional: path to a skill directory. Omit for non-skill evals.
# skill: path/to/my-skill

defaults:
  agent: gemini          # gemini | claude | codex | acp | opencode | command
  model: claude-opus-5   # model the agent answers with (gemini, claude, codex, opencode)
  provider: docker       # docker | local
  trials: 5
  timeout: 300           # seconds
  threshold: 0.8         # for --ci mode
  grader_model: gemini-3-flash-preview  # default LLM grader model
  grader_provider: gemini               # default LLM grader provider: gemini | anthropic | openai
  command: node mycli.js # command to run when agent is 'command' (see Custom Command Agent)
  acp:                   # ACP agent configuration (optional)
    command: gemini --acp  # command to start ACP-compatible agent
    env:                  # optional environment variables
      DEBUG: "1"
  docker:
    base: node:20-slim
    setup: |             # extra commands run during image build
      apt-get update && apt-get install -y jq
  environment:           # container resource limits
    cpus: 2
    memory_mb: 2048

tasks:
  - name: fix-linting-errors
    instruction: |
      Use the superlint tool to fix coding standard violations in app.js.

    workspace:                           # files copied into the container
      - src: fixtures/broken-app.js
        dest: app.js
      - src: bin/superlint
        dest: /usr/local/bin/superlint
        chmod: "+x"

    context:                             # reference material for the agent
      - src: specs/api-schema.yaml       # (not scored — just gives the agent context)
        dest: api-schema.yaml

    graders:
      - type: deterministic
        setup: npm install typescript    # grader-specific deps (optional)
        run: npx ts-node graders/check.ts
        weight: 0.7
      - type: llm_rubric
        rubric: |
          Did the agent follow the check → fix → verify workflow?
        provider: gemini                 # optional: gemini (default) | anthropic | openai
        model: gemini-3.5-flash          # optional model override
        weight: 0.3

    # Per-task overrides (optional)
    agent: claude
    model: claude-sonnet-5       # override the model for this task only
    grader_provider: anthropic   # override default LLM grader provider
    trials: 10
    timeout: 600
String values (instruction, rubric, run) support file references — if the value is a valid file path, its contents are read automatically:
instruction: instructions/fix-linting.md
rubric: rubrics/workflow-quality.mdBoth workspace and context copy files into the agent's working directory, but they serve different roles:
workspace— evaluation fixtures. These are the files the agent works on and graders check against (source code, configs, test inputs).context— reference material. Docs, specs, or schemas that shape how the agent approaches the task but aren't directly graded.
tasks:
  - name: implement-api
    workspace:
      - src: fixtures/app.js          # the file the agent edits
        dest: app.js
    context:
      - src: specs/openapi.yaml       # reference the agent can read
dest: openapi.yamlA task can define turns instead of a single instruction. Each turn has its own instruction and optional graders. The agent's workspace persists across turns — turn 2 sees everything turn 1 produced.
tasks:
  - name: plan-then-implement
    turns:
      - instruction: |
          Read the codebase and propose a refactoring plan. Write it to plan.md.
        graders:
          - type: llm_rubric
            rubric: Is the plan well-structured and comprehensive?
            weight: 0.3
      - instruction: |
          Implement the refactoring plan you wrote in plan.md.
        graders:
          - type: deterministic
            run: bash graders/check-refactor.sh
            weight: 0.7
    workspace:
      - src: fixtures/legacy-app/
        dest: .
A task must have either instruction or turns — never both. Grader results from all turns are aggregated into the trial's final reward.
Agents that implement the optional runTurn() method receive the turn index and all previous outputs for context. Agents without it fall back to the standard run() on each turn.
Expand a single task template into many tasks by loading rows from a JSONL or CSV file:
tasks:
  - name: code-review
    dataset: datasets/review-cases.jsonl
    instruction: |
      Review this code and identify bugs:
      ```
      {{code}}
      ```
    graders:
      - type: deterministic
        run: node graders/check-review.mjs
weight: 1.0datasets/review-cases.jsonl:
{"code": "if (x = 5) { ... }", "expected_issues": "assignment in condition"}
{"code": "arr[arr.length]", "expected_issues": "off-by-one"}
This expands to code-review/0, code-review/1, etc. Template variables use {{key}} syntax — each key in the row is interpolated into the instruction. Each row's full data becomes the task's expected field, so graders can access it via SKILLGRADE_INPUT.
CSV files are also supported — the first row is treated as headers.
A task can carry the row's answer key and a set of labels:
- name: easy--tooltip-token
  instruction: |
    Report the background colour token of the Tooltip's default variant.
    Write {"token": "..."} to answer.json.
  expected:                 # the answer key — graders only, never the agent
    token: Brand/100
    variants: [default, hover]
  metadata:                 # labels for --filter, recorded with the results
    tier: easy
    form: open
    tags: [smoke]
  graders:
    - type: deterministic
      run: node graders/check-token.mjs
Both are optional: a task without expected is scored purely on what its
graders measure, so golden-truth and metric-style tasks live in the same suite.
skillgrade delivers expected, it never interprets it — comparison is the
grader's job. A deterministic grader receives the task context as one JSON
document in SKILLGRADE_INPUT, so expected keeps its structure:
// graders/check-token.mjs — one script for every token task
const { task, trial, expected, metadata } = JSON.parse(process.env.SKILLGRADE_INPUT);
const answer = JSON.parse(fs.readFileSync('answer.json', 'utf8'));   // cwd is the workspace

console.log(JSON.stringify({
  score: answer.token === expected.token ? 1 : 0,
  details: `${task}: want ${expected.token}, got ${answer.token ?? '(none)'}`,
}));
# or from a shell grader
want=$(jq -r .expected.token <<< "$SKILLGRADE_INPUT")An llm_rubric grader gets expected as an ## Expected Output section in its
prompt. Both channels are built after the agent process has exited, and neither
writes to the workspace — unlike run: and rubric:, which are staged into the
agent's working directory before it starts, so keep answer keys out of those.
metadata is what --filter selects on. Values are OR within a key and AND
across keys; --filter and --not-filter are repeatable:
skillgrade --filter=tier=easy,medium              # easy OR medium
skillgrade --filter=tier=hard --filter=form=refuse    # hard AND refuse
skillgrade --filter=tags=smoke --not-filter=tags=flaky
skillgrade --filter-pattern='^easy--'             # regex over task names
skillgrade --filter=tier=easy --list              # print the selection, run nothing
A filter on a key that no task declares is an error rather than a silent
match-everything — --filter=teir=easy should not quietly run the whole suite.
Filters work the same whether the tasks are inline or imported.
Any section can live in another file. $import takes a file, a directory (every
.yaml/.yml inside it, sorted), a glob, or a list of those:
version: "1"

defaults:
  $import: shared/defaults.yaml   # merged in place — keys below win
  trials: 3

tasks:
  - $import: evals/easy/*.yaml    # one task per file, or a file holding a list
  - $import: evals/hard           # a whole directory
    trials: 10                    # applied to every task it imports
  - name: still-inline            # inline tasks keep working
    instruction: ...
    graders: [...]
Each imported file is a normal YAML document — a single task, a list of tasks, or
an object for a section like defaults. Imported files may import further files;
paths are relative to the file that contains the $import, and cycles are an error.
A task keeps working when you move it into its own file: its relative paths
resolve against its own directory first, then the eval root. So
evals/easy/one.yaml can say instruction: instruction.md for the file next to it
while still pointing run: node graders/check.mjs at the shared graders directory
at the root.
Skillgrade ships with three grader types. Mix and weight them to score any dimension — correctness, code quality, workflow compliance, human judgment.
Runs a command and parses JSON from stdout:
- type: deterministic
  run: bash graders/check.sh
  weight: 0.7
Output format:
{
  "score": 0.67,
  "details": "2/3 checks passed",
  "checks": [
    {"name": "file-created", "passed": true, "message": "Output file exists"},
    {"name": "content-correct", "passed": false, "message": "Missing expected output"}
  ]
}
score (0.0–1.0) and details are required. checks is optional.
Bash example:
#!/bin/bash
passed=0; total=2
c1_pass=false c1_msg="File missing"
c2_pass=false c2_msg="Content wrong"

if test -f output.txt; then
  passed=$((passed + 1)); c1_pass=true; c1_msg="File exists"
fi
if grep -q "expected" output.txt 2>/dev/null; then
  passed=$((passed + 1)); c2_pass=true; c2_msg="Content correct"
fi

score=$(awk "BEGIN {printf \"%.2f\", $passed/$total}")
echo "{\"score\":$score,\"details\":\"$passed/$total passed\",\"checks\":[{\"name\":\"file\",\"passed\":$c1_pass,\"message\":\"$c1_msg\"},{\"name\":\"content\",\"passed\":$c2_pass,\"message\":\"$c2_msg\"}]}"
Use
awkfor arithmetic —bcis not available innode:20-slim.
Evaluates the agent's session transcript against qualitative criteria:
- type: llm_rubric
  rubric: |
    Workflow Compliance (0-0.5):
    - Did the agent follow the mandatory 3-step workflow?

    Efficiency (0-0.5):
    - Completed in ≤5 commands?
  weight: 0.3
  provider: gemini           # gemini (default) | anthropic | openai
  model: gemini-2.0-flash    # optional, auto-detected from API key
The provider field selects which LLM API to call:
| Provider | API Key Env Var | Base URL Env Var (optional) | Default Model |
|---|---|---|---|
gemini |
GEMINI_API_KEY |
- | Dynamically resolved latest Flash model (via API) |
anthropic |
ANTHROPIC_API_KEY |
ANTHROPIC_BASE_URL |
Dynamically resolved latest Haiku model (via API) |
openai |
OPENAI_API_KEY |
OPENAI_BASE_URL |
Dynamically resolved latest Mini/Flash model (via API) |
ANTHROPIC_BASE_URL and OPENAI_BASE_URL enable custom/self-hosted endpoints (Ollama, vLLM, etc.). They apply to both LLM grading and skillgrade init.
Pauses the eval for manual review. The grader writes a context file with the agent's output and waits for a reviewer to score it:
- type: human
  prompt: |
    Does the generated UI match the design spec?
    Check layout, colors, and responsive behavior.
  weight: 0.5
When a human grader runs, it:
- Writes the instruction, agent output, and commands to
<workspace>/.review/<task>-<trial>.json - Prints a banner with the file path and scoring instructions
- Polls for
<workspace>/.review/<task>-<trial>.result.json
The reviewer writes a standard grader result:
{"score": 0.8, "details": "Layout matches, colors are off on mobile"}Useful for evaluating subjective quality — design fidelity, UX, documentation clarity — that automated checks can't reliably measure.
graders:
  - type: deterministic
    run: bash graders/check.sh
    weight: 0.7      # 70% — did it work?
  - type: llm_rubric
    rubric: rubrics/quality.md
    weight: 0.2      # 20% — was the approach good?
  - type: human
    prompt: Is the output production-ready?
    weight: 0.1      # 10% — human sign-off
Final reward = Σ (grader_score × weight) / Σ weight
All four extension points use the same registry pattern — register a factory function, use it by name:
import {
  registerGrader, registerAgent, registerProvider, registerReporter,
  Grader, Reporter
} from 'skillgrade';

// Custom grader
class MyGrader implements Grader {
  async grade(workspace, provider, config, taskPath, sessionLog) {
    return { grader_type: 'my_grader', score: 0.9, weight: config.weight, details: 'Passed' };
  }
}
registerGrader('my_grader', () => new MyGrader());

// Custom agent
registerAgent('my-agent', (config) => new MyAgent(config));

// Custom provider (e.g., SSH, E2B, cloud VMs)
registerProvider('ssh', (config) => new SSHProvider(config));

// Custom reporter
class DashboardReporter implements Reporter {
  async report(results, outputDir) {
    // push to your dashboard
    return path.join(outputDir, 'dashboard.json');
  }
}
registerReporter('dashboard', () => new DashboardReporter());Export results in multiple formats — use one or combine them:
skillgrade --smoke --format=json                 # JSON summary
skillgrade --smoke --format=junit                # JUnit XML for CI dashboards
skillgrade --smoke --format=csv                  # CSV for spreadsheets
skillgrade --smoke --format=markdown             # Markdown report
skillgrade --smoke --format=json,junit,markdown # all three at once| Format | Output File | Use Case |
|---|---|---|
json |
summary.json |
Dashboards, trend tracking, programmatic access |
junit |
junit.xml |
CI systems (GitHub Actions, Jenkins, CircleCI) |
csv |
results.csv |
Spreadsheet analysis, data pipelines |
markdown |
report.md |
Documentation, PR comments, Slack posts |
Use --provider=local in CI — the runner is already an ephemeral sandbox, so Docker adds overhead without benefit.
# .github/workflows/skillgrade.yml
- run: |
    npm i -g skillgrade
    cd evals/
    GEMINI_API_KEY=${{ secrets.GEMINI_API_KEY }} skillgrade --regression --ci --provider=local
Exits with code 1 if pass rate falls below --threshold (default: 0.8).
Tip: Use
docker(the default) for local development to protect your machine. In CI,localis faster and simpler.
| Variable | Used by |
|---|---|
GEMINI_API_KEY |
Agent execution, LLM grading (provider: gemini), skillgrade init |
ANTHROPIC_API_KEY |
Agent execution, LLM grading (provider: anthropic), skillgrade init |
OPENAI_API_KEY |
Agent execution (Codex), LLM grading (provider: openai), skillgrade init |
ANTHROPIC_BASE_URL |
LLM grading (provider: anthropic), skillgrade init — custom Anthropic-compatible endpoint |
OPENAI_BASE_URL |
LLM grading (provider: openai), skillgrade init — custom OpenAI-compatible endpoint (Ollama, vLLM, etc.) |
GEMINI_MODEL |
Override the default model used for Gemini LLM grading (defaults to dynamic API lookup; throws if resolution fails) |
INIT_GEMINI_MODEL |
Override the model used for Gemini in skillgrade init (defaults to GEMINI_MODEL or dynamic API lookup; throws if resolution fails) |
ANTHROPIC_MODEL |
Override the default model used for Anthropic LLM grading (defaults to dynamic API lookup; throws if resolution fails) |
INIT_ANTHROPIC_MODEL |
Override the model used for Anthropic in skillgrade init (defaults to ANTHROPIC_MODEL or dynamic API lookup; throws if resolution fails) |
OPENAI_MODEL |
Override the default model used for OpenAI LLM grading (defaults to dynamic API lookup; throws if resolution fails) |
INIT_OPENAI_MODEL |
Override the model used for OpenAI in skillgrade init (defaults to OPENAI_MODEL or dynamic API lookup; throws if resolution fails) |
Variables are also loaded from .env in the working directory. Shell values override .env. All values are redacted from persisted session logs.
Point skillgrade at any command — a custom script, an orchestrator over the Claude/OpenAI SDKs, or any CLI tool — without forking the package or implementing an ACP server.
skillgrade --agent=command --command="node mycli.js"Or in eval.yaml:
defaults:
  agent: command
  command: "node mycli.js"
  provider: local        # run on the host; or use docker + docker.setup to install your CLI
command can also be set per task to override the default.
The task instruction is piped to your command's stdin (skillgrade writes it to /tmp/.prompt.md, then runs cat /tmp/.prompt.md | <command> inside the workspace directory). If your CLI takes the prompt as an argument instead, wrap it in a one-line script that reads stdin.
Your command runs in the workspace and is free to read/edit files there — graders score the resulting workspace state (and any live checks), not your command's stdout, so any agent slots in cleanly.
provider: localis the simplest fit for a custom agent: your command runs on the host with your tools already installed.provider: dockerstill works — skillgrade does not auto-install anything for thecommandagent, so install your CLI and dependencies viadocker.setup:
defaults:
  agent: command
  command: "mycli run"
  docker:
    base: node:20-slim
    setup: "npm install -g my-cli-package"
OpenCode is an AI coding agent that supports multiple AI models and specialized subagents.
# Use OpenCode with default agent and model
skillgrade --agent=opencode

# Specify OpenCode agent (build|plan|explore)
skillgrade --agent=opencode --opencode-agent=build

# Specify both agent and model (provider/model format)
skillgrade --agent=opencode --opencode-agent=build --opencode-model=anthropic/claude-sonnet-4-20250514| Agent | Description |
|---|---|
build |
Default primary agent with full tool access |
plan |
Read-only planning/analysis agent |
explore |
Fast codebase exploration agent |
Models are specified in provider/model format:
| Model | Format |
|---|---|
| Claude Sonnet 4 | anthropic/claude-sonnet-4-20250514 |
| GPT 5.1 Codex | opencode/gpt-5.1-codex |
| Flag | Description |
|---|---|
--agent=opencode |
Use OpenCode agent |
--opencode-agent=NAME |
OpenCode agent (build|plan|explore) |
--opencode-model=MODEL |
OpenCode model (provider/model format) |
- skillgrade invokes OpenCode CLI with
opencode run - Passes instruction via temp file to avoid shell escaping issues
- Supports both agent and model specification
- Works with
--provider=dockeror--provider=local
Agent Client Protocol (ACP) is an open protocol that standardizes communication between AI coding agents and clients. Using an ACP-compatible agent allows you to evaluate agents without managing API keys directly.
# Use Gemini CLI in ACP mode (requires gemini CLI installed)
skillgrade --agent=acp --acp-command="gemini --acp"

# Or configure in eval.yamldefaults:
agent: acp
acp:
command: gemini --acpAny agent that supports the ACP protocol can be used:
| Agent | Command |
|---|---|
| Gemini CLI | gemini --acp |
| Other ACP agents | Check agent documentation |
- skillgrade starts the ACP agent as a subprocess
- Communication happens via JSON-RPC 2.0 over stdio
- No API key required — authentication is handled by the ACP agent
- Works best with
--provider=localsince the ACP agent needs to be available in your environment
| Flag | Description |
|---|---|
--agent=acp |
Use ACP-compatible agent |
--acp-command=CMD |
Command to start the ACP agent |
The --acp-command can also be set in eval.yaml under defaults.acp.command.
- Grade outcomes, not steps. Check that the file was fixed, not that the agent ran a specific command.
- Instructions must name output files. If the grader checks for
output.html, the instruction must tell the agent to save asoutput.html. - Validate graders first. Use
--validatewith a reference solution before running real evals. - Start small. 3–5 well-designed tasks beat 50 noisy ones.
- Combine grader types. Deterministic for correctness, LLM for quality, human for subjective judgment — weight each to match what matters.
For a comprehensive guide on writing high-quality skills, check out skills-best-practices. You can also install the skill creator skill to help author skills:
npx skills add mgechev/skills-best-practicesMIT
Inspired by SkillsBench and Demystifying Evals for AI Agents.